
Making Kubernetes AI-Ready for NVIDIA Vera Rubin on Day One
Configuring and optimizing Kubernetes for new GPU hardware such as NVIDIA Vera Rubin is complex and error-prone. Drivers, kernels, runtimes, networking,...
Follow the latest facts and developments on one topic.
Configuring and optimizing Kubernetes for new GPU hardware such as NVIDIA Vera Rubin is complex and error-prone. Drivers, kernels, runtimes, networking,...
NVIDIA DSX AI Factory Platform brings together technologies to help the ecosystem design, build, and operate more efficient AI factories, including open source,...
NVIDIA released Auto Ontology, an Apache 2.0 library that generates a semantic layer from enterprise metadata. It grounds agent SQL in certified definitions and serves context through MCP, CLI and API. The post NVIDIA Releases Auto Ontology: An Open Semantic Layer That Grounds AI Agent SQL appeared first on MarkTechPost.

We checked out the ASRock Rack booth at OCP 2026 and saw servers ranging from fully integrated NVIDIA NVL72 racks to liquid-cooled switches The post Liquid-Cooled NVIDIA Servers at the ASRock Rack OCP 2026 Booth appeared first on ServeTheHome.

On the evening of October 31, the DeepSeek Harness team published a technical article titled “Exploring Super-Agent Design: Toward More Autonomous Agent Systems” on their official WeChat account. DeepSeek stated that advances in model capabilities have given rise to new application paradigms, with personal assistants (Personal Agents) beginning to emerge in large numbers. However, current mainstream agent designs still struggle to support this approach at scale across multiple tasks and team collaboration...

When investors get nervous about AI spending, it helps to have the chipmaker that sells the chips offer to cosign the loan.

Teams building AI applications need a repeatable path from a model configuration to a working inference endpoint. NVIDIA Dynamo is a distributed inference...
Building an autonomous agent requires a model, a harness, and domain-specific tools. To deploy an agent more securely, developers need a runtime that enforces...
Most reports focus only on Kimi K3’s 1.68x speed boost, overlooking a key warning from the vLLM blog: AI-generated inference code is now so fast that humans can’t keep up with line-by-line scrutiny. NVIDIA engineers leveraged AI to write a 12,000-line Megakernel, squeezing maximum performance out of the model without upgrading hardware. The center of gravity in the compute power race has shifted toward software stacks, and the human-in-the-loop paradigm is being redefined.
NVIDIA and a team from MIT have released the model weights for the Open-H3-Regenerate-2K video enhancement project on Hugging Face.
NVIDIA has officially open-sourced its new large-scale speech transcription model, Nemotron 3.5 Transcribe. Designed for professional voice processing, this model leads the industry in key metrics such as multilingual transcription accuracy, long-audio handling, and multi-speaker separation. It employs a Mixture of Experts (MoE) architecture with approximately 34 billion total parameters, activating only a subset of these parameters during each forward pass to enhance efficiency. Overall, it provides a new open-source option for professional speech transcription.

A top executive of a Singapore AI cloud company that was accused of illegally selling Nvidia chips to China could also have been a Chinese spy, sources have told the New York Times.

NVIDIA Nemotron 3.5 Super VL is a 120B-parameter mixture-of-experts model that pairs reasoning and tool use with multimodal understanding. This post explores its architecture and use cases, then shows how to deploy it on Amazon EKS, EKS Auto Mode, and Amazon SageMaker HyperPod EKS with NVIDIA Dynamo and vLLM.
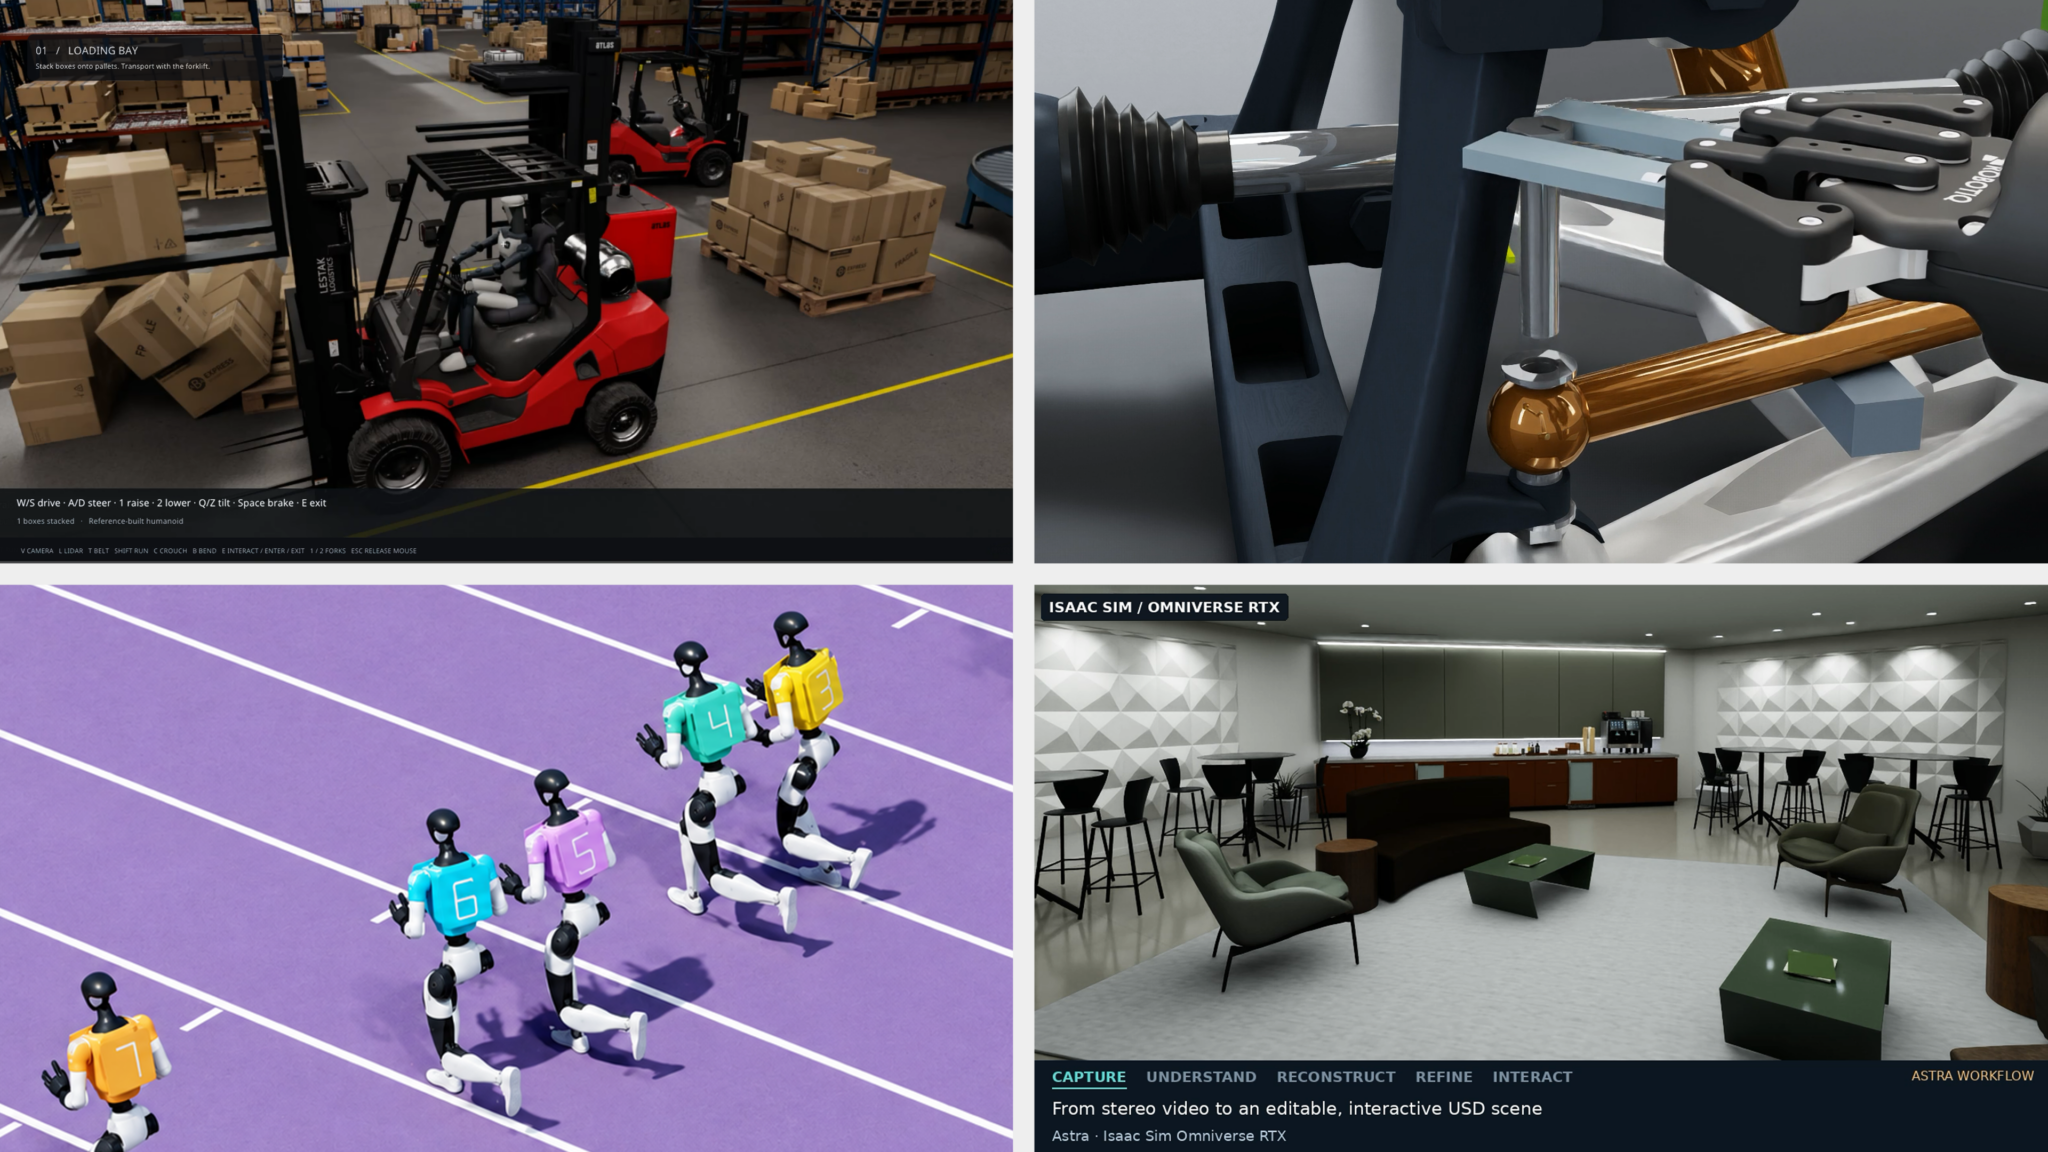
Turning a simulation idea into a working application means assembling assets, connecting physics and rendering, and checking that the scene behaves as intended. Developers are combining frontier AI models with NVIDIA Omniverse libraries to help carry out that work — building applications for exploring scenarios, investigating failures and improving designs. Developers direct AI agents through […]
## New Models ### Mistral Large 4 (Le Chonk) Mistral Large 4 is Mistral's largest and most capable model to date: a 1 trillion-parameter natively multimodal Mixture-of-Experts model with 49 billion active parameters per token (52 billion including embeddings and output layers), trained from scratch on 3,800 NVIDIA Grace Blackwell GPUs in Mistral's own datacenters in Europe. Mistral Large 4 unifies instruction following, reasoning, coding, and agentic workflows in a single set of weights. While a generalist model, it shows especially good performance on workloads such as cybersecurity, finance, and law, and it surpasses frontier closed models on visual grounding. It is natively fluent in 160+ languages, including every official language of the European Union. #### Key Features Mistral Large
Nvidia Corp. today released a leaderboard-winning open artificial intelligence model for multilingual audio transcription and translation, along with an open data pipeline for fine-tuning Nemotron 3.5 Transcribe. Traditional transcription AI models follow a workflow that detects speech, transcribes it, identifies and labels different speakers, then answers questions about the transcription. Transcribe does all of this […] The post Nvidia releases all-in-one adaptable Nemotron 3.5 audio transcription and translation model appeared first on SiliconANGLE.
NVIDIA RTX Spark powers thin and light laptops built for everything that developers, creators and gamers do. RTX Spark laptops are now available from ASUS, Dell, HP, Lenovo, Microsoft and MSI. These powerful systems combine an NVIDIA Blackwell RTX GPU and an NVIDIA Grace CPU in a single superchip with up to 128GB of unified […]
Nvidia just released a free speech-to-text model that can transcribe up to 40 languages, but it only works on recordings, not live audio, so it’s a big step for meeting and medical transcription tools while still leaving real-time use to rivals like ElevenLabs.

DeepSeek, Google, and NVIDIA build the agent stack
On October 28, it was reported that OpenAI plans to procure AI chips from Google. For a long time, OpenAI has been a major purchaser of NVIDIA GPUs, relying on them for training and inference of large-scale models. As computing power demands surge, companies are seeking more cost-effective alternatives suitable for running AI models. Google’s self-developed TPUs have gradually gained prominence in recent years, emerging as a potential option. This move may reflect a trend toward diversification in AI chip procurement.
