Skip to content
AI NEWS JOURNAL
FOLLOW THE THREAD

DeepSeek

Follow the latest facts and developments on one topic.

Newest first

Show HN: Umbel – Remote-control agent CLIs over tmux

Been using this in all my sessions the last months. Opus 5.5 (over MCP) spawns Deepseek flash agents - and codex for audits etc. Very curious to hear what the HN crowd thinks/makes of it. Comments URL: https://news.ycombinator.com/item?id=50383189 Points: 1 # Comments: 0

GC-MoE: Overlapping Expert-Parallel Token Dispatch with FP8/FP4 Grouped GEMM via CUDA Green Contexts

arXiv:2611.04222v1 Announce Type: new Abstract: Under expert parallelism, mixture-of-experts (MoE) layers pay all-to-all token dispatch, grouped GEMMs, and a combine step in every layer. In decode each rank holds only 1-256 tokens: dispatch latency and weight traffic dominate while tensor-core utilization is inherently low. In fused operators such as DeepGEMM's Mega MoE, dispatch and computation overlap only by sharing every SM: dispatch warps compete with TMA/MMA and epilogue warps for registers, shared memory, and issue slots; every phase shares one CTA resource budget, synchronization spans the whole SM array, and every replay ends with a workspace-clean pass and a cross-rank barrier. We present GC-MoE, an open-source FP8/FP4 MoE inference operator for NVIDIA Hopper and Blackwell GPUs that uses CUDA Green Contexts to split the device into a small communication partition and a large compute partition. Each role gets its own kernel, resource budget, and synchronization domain, so dispatch and GEMM tune independently. A three-node CUDA Graph (four on Hopper with fused shared experts) launches the dispatch and grouped-GEMM kernels as concurrent roots; a token-ring handshake starts computation on the first filled ring blocks, and double-buffered receive counters remove the trailing cross-rank barrier between replays. The compute partition runs operand-swapped tcgen05 block-scaled MMA on Blackwell and register-A WGMMA with in-register FP4 decoding on Hopper, with fused SwiGLU, requantization, and optional shared experts. On 8 H20 GPUs GC-MoE accelerates DeepSeek-V4.1-Flash decode by 1.188x on average on both the routed and shared-expert suites (peaks 1.296x and 1.353x); on 8 B300 GPUs it accelerates GLM-5.2 and DeepSeek-V4.1-Flash by 1.106x (1.123x with fused shared experts, peak 1.209x), beating Mega MoE at all 54 measured points at matched accuracy. GC-MoE reserves only 20 of 148 SMs on B300 for dispatch.

DouBao Work has officially integrated with DeepSeek, Kimi, and GLM, making enterprise procurement hassle-free.

On October 29, according to Kuai Technology, DouBao Work under ByteDance launched a brand-new third-party large model service for corporate clients. This service breaks the previous practice of companies separately purchasing models from different vendors; users can now seamlessly switch among multiple mainstream large models within the same workspace, tailored to tasks such as long-text processing, code writing, and logical reasoning. The initial rollout includes three industry-leading models.

豆包工作正式接入DeepSeek、Kimi与GLM,企业采购彻底省心了
Timeline and related coverage

Is the next “big” wave coming? DeepSeek V5 has appeared in the official code repository, with the new-generation flagship model expected to debut in November.

On October 28, users noticed that DeepSeek had once again changed its large-model fingerprint, sparking speculation about the imminent release of a major new model. The official DeepSeek Harness codebase now includes code for DeepSeek-V5, V5-open, and V5-next. Currently, the V5-related content mainly consists of placeholders, but it indicates that the mechanism for releasing the new model is already in place.

下一波“大的”要来了?DeepSeek V5 现身官方代码库,新一代旗舰模型预计 11 月登场
Timeline and related coverage

b11934

tests : speed up tensor data generation and model saving (#31145) * tests : speed up tensor data generation and model saving Refactor save_models to create only the model, not a llama_context, which is not needed for saving. Replace the slow std::normal_distribution draw with a splitmix64 + box-muller normal generator. Assisted-by: dsh:llama.cpp/ggml-org/DeepSeek-V4-Flash-Vision-Exp-GGUF (Mac Studio, M2 Ultra, 192GB) * tests : use a shared pool of normal draws for tensor data Generate a pool of normal draws once with std::mt19937 and std::normal_distribution, then have every tensor copy a cyclic slice of it instead of running a per-tensor box-muller. The name-keyed slice selection keeps the draw deterministic. Assisted-by: dsh:llama.cpp/ggml-org/DeepSeek-V4-Flash-Vision-Exp-GGUF (Mac Studi

Timeline and related coverage

b11926

glm5-next : QSA without kq_mask (+ DSA) (#31009) * glm5-next : QSA without kq_mask * DSA: dsa top-k mask change tested with layers 0,3 of DeepSeek-V3.2 **Website:** - **Attestations:** - **macOS/iOS:** - [macOS Apple Silicon (arm64)](https://github.com/ggml-org/llama.cpp/releases/download/b11926/llama-b11926-bin-macos-arm64.tar.gz) - macOS Apple Silicon (arm64, KleidiAI enabled) [DISABLED](https://github.com/ggml-org/llama.cpp/pull/23780) - [macOS Intel (x64)](https://github.com/ggml-org/llama.cpp/releases/download/b11926/llama-b11926-bin-macos-x64.tar.gz) - [iOS XCFramework](https://github.com/ggml-org/llama.cpp/releases/download/b11926/llama-b11926-xcframework.zip) **Linux:** - [Ubuntu x64 (CPU)](https://github.com/ggml-org/llama.cpp/releases/download/b11926/llama-b11926-bin-ubuntu-x64.t

Timeline and related coverage

MiniMax M3.1Flash release sparks “questionable results” concerns: high scores on old questions, failure on new ones, and an illusion rate as high as 92.8%

On October 19, 2026, MiniMax released its low-cost large model, M3.1Flash, which scored 42 points in comprehensive evaluations and boasts a 70% reduction in cost compared to the previous generation. However, it immediately faced accusations of “cheating on exam questions”: on AA’s publicly available past papers, it nearly achieved a perfect score, yet continued to produce the original answers even after the question stems were rewritten. Reviewers such as Cat Boss and Binkg pointed out that its performance on old and new questions is sharply divided, token consumption is abnormal, and its hallucination rate in knowledge tests reaches as high as 92.8%. On October 23, MiniMax open-sourced the model weights for independent verification, but the mechanisms behind its question-identification capabilities and the reasons for discrepancies in Chinese–English responses remain unresolved.

Why it matters:This report is based on multi‑party empirical testing (including Binkg’s re‑title experiment, the author’s replication, and a dual evaluation comparison between AA and Plotly‑Mila), verifiable data (token counts, prices, accuracy/hallucination rates), and contradictions in model behavior (English errors vs. Chinese correctness, stable performance on old tasks vs. collapse on new ones). It systematically lays out the core symptoms of the current credibility crisis in large‑model evaluations: high scores do not necessarily equate to strong generalization, and low‑price advantages create tension with the reality of model capabilities. The information source is a deep investigation authorized for publication by Titanium Media, complete with original test procedures, screenshot evidence, and timestamps, offering both timeliness and rich detail.

Timeline and related coverage

Multi-Agent Retrieval-Augmented Causality Assessment (MARCA) of Individual Case Safety Reports in Pharmacovigilance

arXiv:2610.33279v1 Announce Type: new Abstract: Introduction: Increasing volumes of individual case safety reports (ICSRs) challenge expert-led causality assessment in pharmacovigilance. We developed MARCA (Multi-Agent Retrieval-Augmented Causality Assessment), a four-agent framework for Naranjo-based assessment, and evaluated agreement with human experts and exploratory differences between non-RAG and RAG-labelled scores. Methods: MARCA combined scientific literature retrieval, drug-label assessment, objective-evidence classification, and clinical causality reasoning using Gemini 2.5 Pro and DeepSeek-V3.2. Agent-generated rationales informed human-assisted scoring. A consensus expert reference standard covered 215 ICSRs and 1,562 drug-event combinations (DECs) from FAERS (Q1-Q2 2025). Agr

Timeline and related coverage

Tencent QClaw will be discontinued on December 24, 2026, as Chinese tech giants accelerate the integration of their AI products into general-purpose assistants.

According to a report by Titanium Media on October 26, 2026, Tencent’s AI product QClaw will officially shut down on December 24, 2026, having operated for only 188 days since its public beta launch in March 2026; users will be redirected to WorkBuddy. This case exemplifies the widespread “quick launch, quick exit” pattern among eight leading Chinese AI companies—including Alibaba, Baidu, and ByteDance—across ten major AI market segments: standalone AI applications are rapidly giving way to general-purpose assistants, with the industry’s focus now shifting toward personal intelligent agents.

Why it matters:The material is based on timely reports published by Titanium Media (tmtpost.com), with a publication time of 2026-10-26T23:23:04Z, which predates the shutdown date and aligns with the site’s time zone (Asia/Singapore). The content covers verifiable entities, specific timelines, and cross-company behavioral patterns, without relying on external sources that were not provided.

Timeline and related coverage

Which Answer Did the Seventeen-Year-Old Write? A Behavioral Case Study of Author-Age Misattribution, Miscalibrated Confidence, and Non-Corrective Self-Explanation in Six Frontier Language Models

arXiv:2610.31946v1 Announce Type: new Abstract: Three students answered the same exam prompt by hand: "What is happiness? Are you happy?" Their ages, recorded at collection, are 17, 28, and 45. The 17-year-old's answer is hedged and formally phrased. Asked to match each answer to an age and gender label, most frontier language models confidently assign it to an adult. This paper reports a structured case study of that failure across six models: Claude Fable 5, Gemini 3.1 Pro, GPT-5.6 Sol, Grok 4.5, GPT-4o (2024), and DeepSeek V4. We ran 1,081 API sessions and scored 3,225 responses across six experimental conditions that manipulate framing, disclosure format, and audience-awareness instruction. Three of six models perform at or near chance (1/3) on the matching task while reporting 73-88%

Timeline and related coverage

HyScale: Scaling Long-Context Training for Learned Sparse Attention

arXiv:2610.32057v1 Announce Type: new Abstract: We present HyScale, a long-context training system for learned sparse attention. Learned sparse attention is a promising architecture for million-token contexts, widely adopted in production since DeepSeek-V3.2. Selection, however, grows into the training bottleneck. For each query, it scores every previous token whereas sparse attention reads only $k$; worse, current systems materialize a full score table and repeat selection during recomputation. Our key insight is that the output of selection is not an activation, but rather a set of indices. Building on it, HyScale introduces HyTopK and selection replay. HyTopK finds each query's exact top-$k$ on the fly without a score table, while selection replay reuses forward-pass selection in recomp

HyScale: Scaling Long-Context Training for Learned Sparse Attention
Timeline and related coverage

b11881

llama : respect no_alloc in all memory caches (#31087) * llama : respect no_alloc in memory caches Assisted-by: dsh:llama.cpp/ggml-org/DeepSeek-V4-Flash-Vision-Exp-GGUF (Mac Studio, M2 Ultra, 192GB) * llama : TODO: move no_alloc out of llama_hparams Assisted-by: dsh:llama.cpp/ggml-org/DeepSeek-V4-Flash-Vision-Exp-GGUF (Mac Studio, M2 Ultra, 192GB) * llama : TODO: move no_alloc out of llama_hparams Assisted-by: dsh:llama.cpp/ggml-org/DeepSeek-V4-Flash-Vision-Exp-GGUF (Mac Studio, M2 Ultra, 192GB) **Website:** - **Attestations:** - **macOS/iOS:** - [macOS Apple Silicon (arm64)](https://github.com/ggml-org/llama.cpp/releases/download/b11881/llama-b11881-bin-macos-arm64.tar.gz) - macOS Apple Silicon (arm64, KleidiAI enabled) [DISABLED](https://github.com/ggml-org/llama.cpp/pull/23780) - [macOS

Timeline and related coverage

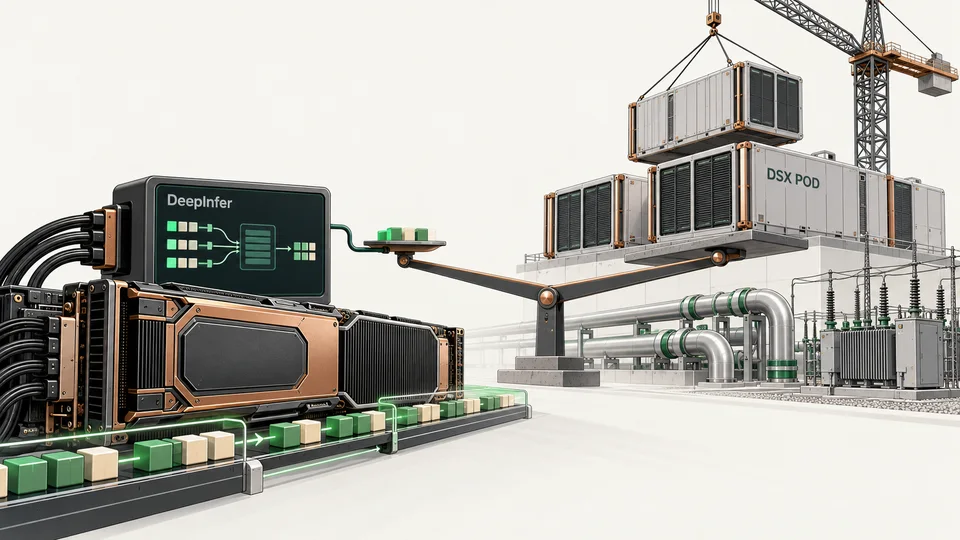
Low-Cost Intelligence vs. Expensive Ambitions: DeepInfer, DSX POD, and AI Investment Expansion

Issue 958 of “The Sequence Radar” examines inference software, modular AI factories, and enterprise AI investments side by side: cheaper per-inference does not necessarily mean lower overall industry spending. This article is compiled from the original publication and supplemented with technical scope and delivery terms based on DeepSeek and NVIDIA’s official materials.

推理软件效率与模块化AI基础设施投入的编辑示意,非实际产品照片
Timeline and related coverage

AI-driven market trends don’t undermine earnings—only valuations: Q3 reports confirm order visibility, and investors are bucking the trend by increasing positions.

From September 22 to October 22, 2026, the A-share AI sector continued to adjust, with the ChiNext Index falling 24.20% and the STAR 50 PE-TTM dropping nearly 60%, from 264 times to above 110 times. Meanwhile, corporate earnings collectively exceeded expectations during the same period—CATL reported a quarterly net profit of RMB 21.2 billion, Yuanjie Technology forecast a nearly sixfold increase, and Lianxun Instruments posted a net profit surge of over 18 times—while equity ETFs saw net inflows of nearly RMB 70 billion. The core driver of this correction was valuation compression, rather than deteriorating fundamentals.

Why it matters:The material explicitly states that the primary drivers of this round of decline are the rising discount rate (affecting the denominator) and weakening overseas regulatory expectations (eroding confidence on the numerator), which together have weighed on valuations—while industry conditions, order visibility, primary-market pricing, and policy‑exemption arrangements have all remained stable. Meanwhile, continued net ETF subscriptions and a spate of announcements from optical‑module companies indicating order backlogs extending through 2027 further confirm that the market is actively stepping in at low valuation levels, with a clear rationale and a fully substantiated chain of evidence.

Timeline and related coverage

DeepSeek V4.1 Flash, MiniMax M3.1 Flash, and Mercury 3 have been released; model regulation in China and the U.S. has been upgraded; Anthropic has launched a public-interest fund and an AI legislation draft.

DeepSeek V4.1, Flash 1017, and two other new models have been released, but they remain in the early deployment phase; China and the U.S. are simultaneously strengthening AI governance: the U.S. Department of Homeland Security has banned DeepSeek-related products, while China plans to impose export approval for ultra-large-scale models; Anthropic has launched a public-interest equity fund and drafted a federal AI bill; industry infrastructure and security research are advancing in tandem.

Timeline and related coverage

DeepSeek V4.1 Flash, MiniMax M3.1 Flash, and Mercury 3 were released simultaneously, as debates over AI infrastructure and governance continue to intensify.

From October 16 to 19, 2026, three new models—DeepSeek V4.1 Flash 1017, MiniMax M3.1 Flash (Space Bunny), and Mercury 3 (Inception)—were released in quick succession. At the same time, the U.S. Department of Homeland Security ordered a ban on DeepSeek-related products, while China is drafting export control regulations for ultra-large-scale models, bringing the conflicts among the open-source ecosystem, computing infrastructure, and AI governance into sharp focus.

Timeline and related coverage