
Show HN: One-script installer for TRELLIS.2 on Nvidia Blackwell under WSL2
Article URL: https://github.com/Creepybits/trellis2-blackwell-wsl Comments URL: https://news.ycombinator.com/item?id=50403233 Points: 1 # Comments: 0
Search headlines, summaries and articles to connect the dots.
Article URL: https://github.com/Creepybits/trellis2-blackwell-wsl Comments URL: https://news.ycombinator.com/item?id=50403233 Points: 1 # Comments: 0
Zyphra released ZYFA, open-source FP8 and BF16 prefill attention kernels for AMD Instinct MI355X. On real model activations, its FP8 kernels run 1.16-1.76x faster than AMD’s AITER, with 62-78% lower error at head dimension 128. The post Zyphra ZYFA: FP8 FlashAttention for AMD MI355X, Up to 1.76x Faster appeared first on MarkTechPost.
How vLLM migrated its CUDA build and compiled dependencies to the LibTorch Stable ABI, enabling compatible PyTorch upgrades without rebuilding vLLM.
arXiv:2611.07105v1 Announce Type: new Abstract: For sufficiently large transformer-based Large Language Models (LLMs), whose parameters cannot be retained in on-chip caches, prefill throughput on multi-socket CPUs is often limited by sustainable DRAM bandwidth rather than peak floating-point throughput. In the standard PyTorch compilation (i.e., TorchInductor) path, model weights are allocated without considering the Non-Uniform Memory Access (NUMA) topology: specifically, the affinity between memory banks and compute cores is disregarded. This causes a substantial fraction of weight accesses to traverse the inter-socket interconnect, severely degrading the effective memory bandwidth available to each socket. We address this bottleneck through a compiler-level solution that makes TorchInductor NUMA-aware. Treating each NUMA socket as an independent tensor-parallel partition, we introduce NUMA-aware Tensor Parallelism (NUMA-TP). This approach transparently shards weights across sockets and schedules compute kernels such that thread pools and memory allocations remain strictly local to their respective sockets using CPU affinity. We evaluate the approach on GPT-2 (117M, 345M, 762M) and BERT (Small, Large), which exercise standard multi-head attention and MLP, as well as Gemma 3 270M, which combines Multi-Query Attention with a GeGLU-gated MLP. By strictly enforcing data locality, our approach successfully mitigates cross-socket traffic, achieving prefill speedups of up to 2.63x on a dual-socket Haswell platform, up to 1.87x on a dual-socket Cascade Lake platform, and up to 2.27x on a four-socket Haswell-EX platform.
Phonon, a small text-to-speech model that runs entirely on the user's device without requiring internet access, has been released with support for English, French, German, Spanish, and Portuguese. Built on the Pocket TTS lineage using flow matching, Phonon achieves high-quality audio in compact sizes (65 MB and 75 MB), with the 31m version licensed under Apache 2.0 for commercial use. It excels in intelligibility and speed, ranking first in German and Spanish on Hugging Face's Open TTS Leaderboard and leading in CPU streaming benchmarks. The model supports voice cloning, custom voices via Gradium Studio, and integrates with Hugging Face Transformers. It is available in multiple formats and backends, including WebAssembly, GPU, and NPU, enabling deployment across phones, laptops, single-board computers, and browsers. Over 200,000 downloads were recorded in its first two weeks, with active developer adoption through tools like ExecuTorch, Micdrop, and Spaces. Future developments include support for additional languages, smaller models, and custom vocabulary fine-tuning.
The Call for Proposals for PyTorch Day China 2026 closes November 10 at 23:59 China Standard Time. The event takes place in Beijing on December 12, bringing together PyTorch developers,... The post Call for Proposals: PyTorch Day China 2026 appeared first on PyTorch.
The Call for Proposals for PyTorch Day China 2026 closes November 10 at 23:59 China Standard Time. The event takes place in Beijing on December 12, bringing together PyTorch developers,... The post Final Call for Proposals: PyTorch Day China 2026 appeared first on PyTorch.
Seekable OCI (SOCI) indexing for Amazon SageMaker AI training and processing jobs takes full container image download off the critical path. SageMaker AI lazy-loads your image to start containers in seconds instead of minutes, with no changes to your job definition. See the benchmarks and how to adopt it.
Mirendil released Fern 0.1, its first model, pretrained from scratch with a 10M-token context window. It targets agentic AI R&D work, scores 100% on RULER single needle at 10M, but trails frontier models on agentic coding. The post Mirendil Launches Fern 0.1, Its First Model, With 10M-Token Context appeared first on MarkTechPost.
## What's Changed * model_prefetch: syncrhonize all graph cleanups by @rattus128 in https://github.com/Comfy-Org/ComfyUI/pull/17178 * Add rope scaling support to MOSS-image by @kijai in https://github.com/Comfy-Org/ComfyUI/pull/17172 * [Partner Nodes] Renew partner-node sign-in tokens in API nodes by @dante01yoon in https://github.com/Comfy-Org/ComfyUI/pull/16943 * [Partner Nodes] feat(HeyGen): add HeyGen Voice instant clone and text-to-speech by @bigcat88 in https://github.com/Comfy-Org/ComfyUI/pull/17043 * [Partner Nodes] feat(ClarityAI): add Crystal Video Upscaler node by @bigcat88 in https://github.com/Comfy-Org/ComfyUI/pull/17192 * [Partner Nodes] feat(BFL): add 2K/4K resolutions to FLUX 3 Video nodes by @bigcat88 in https://github.com/Comfy-Org/ComfyUI/pull/17200 * Support MOSS-image
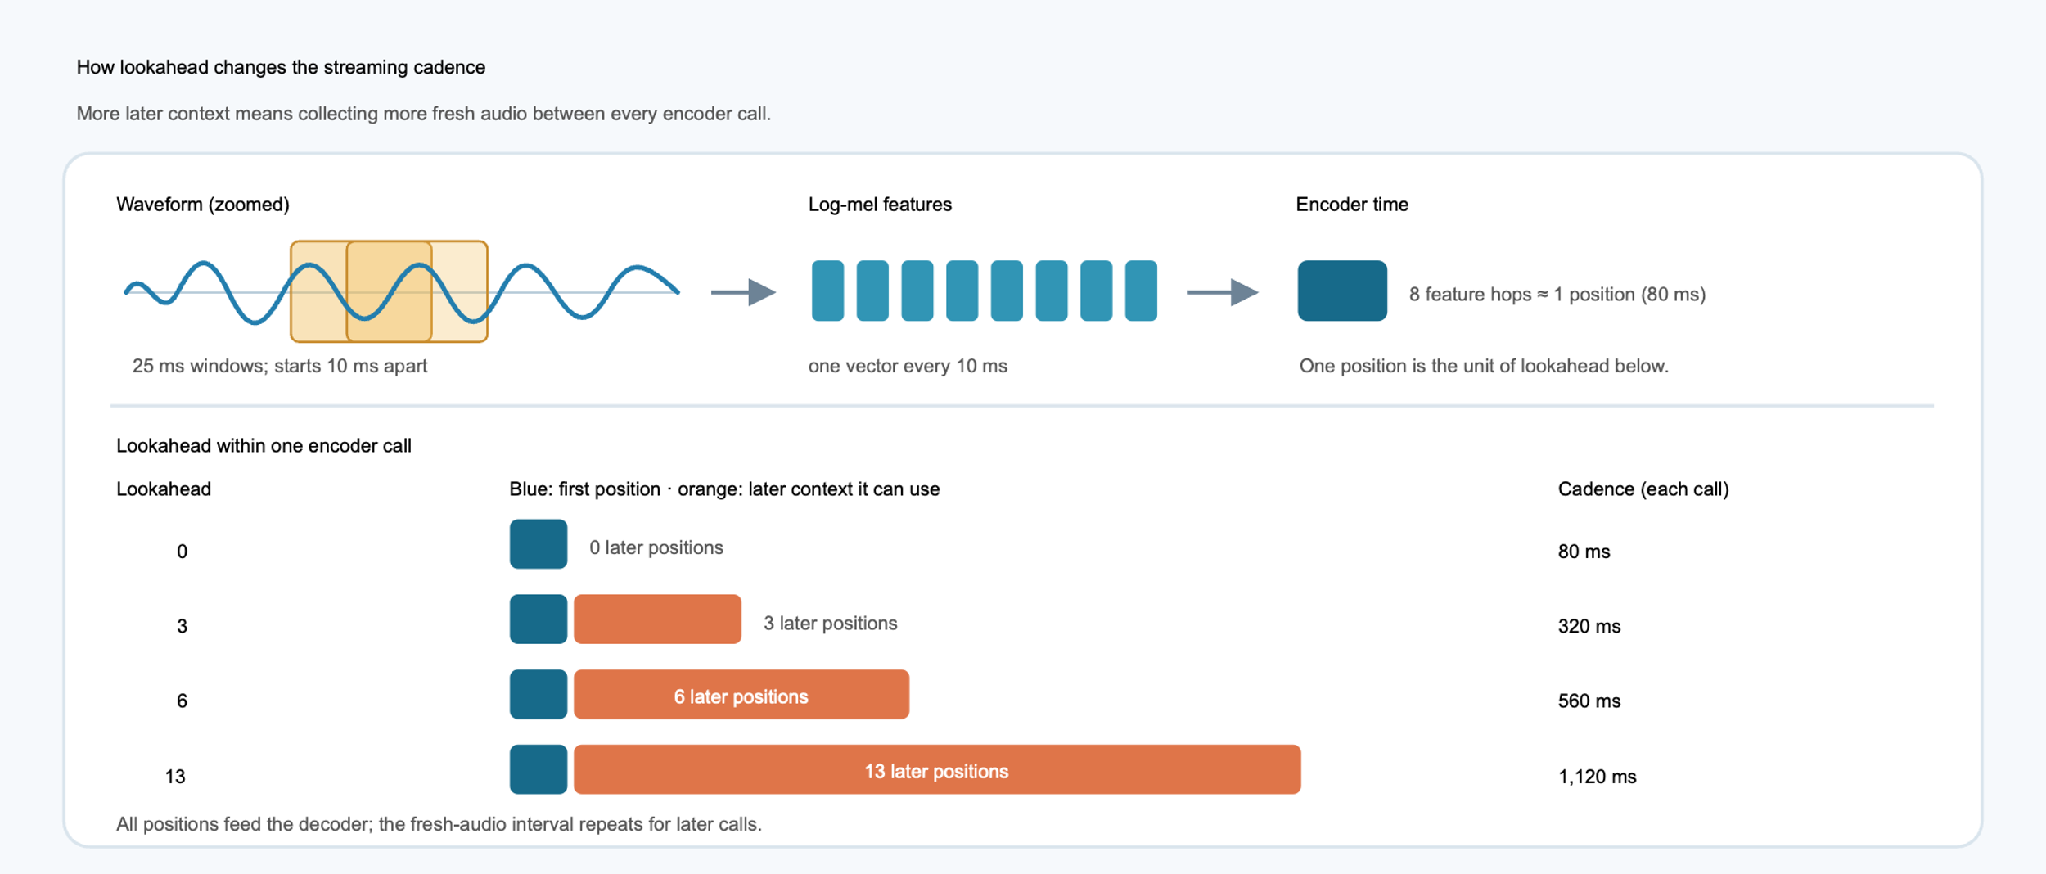
When you’re speaking to a device, you expect text to appear as you talk. That makes streaming automatic speech recognition (ASR) a different challenge from batch transcription, where the model... The post Optimizing Streaming Speech Recognition on Arm® Edge Devices with ExecuTorch appeared first on PyTorch.

Fleet-wide computer vision needs a model per camera, not one model for the whole fleet. This post presents a working Amazon SageMaker SDK v3 reference architecture that trains, quality-gates, compiles per-camera models with SageMaker Neo, and versions thousands of them, with an AWS Step Functions layer pacing fleet-scale retraining within account quotas.
What is “night” to a machine?
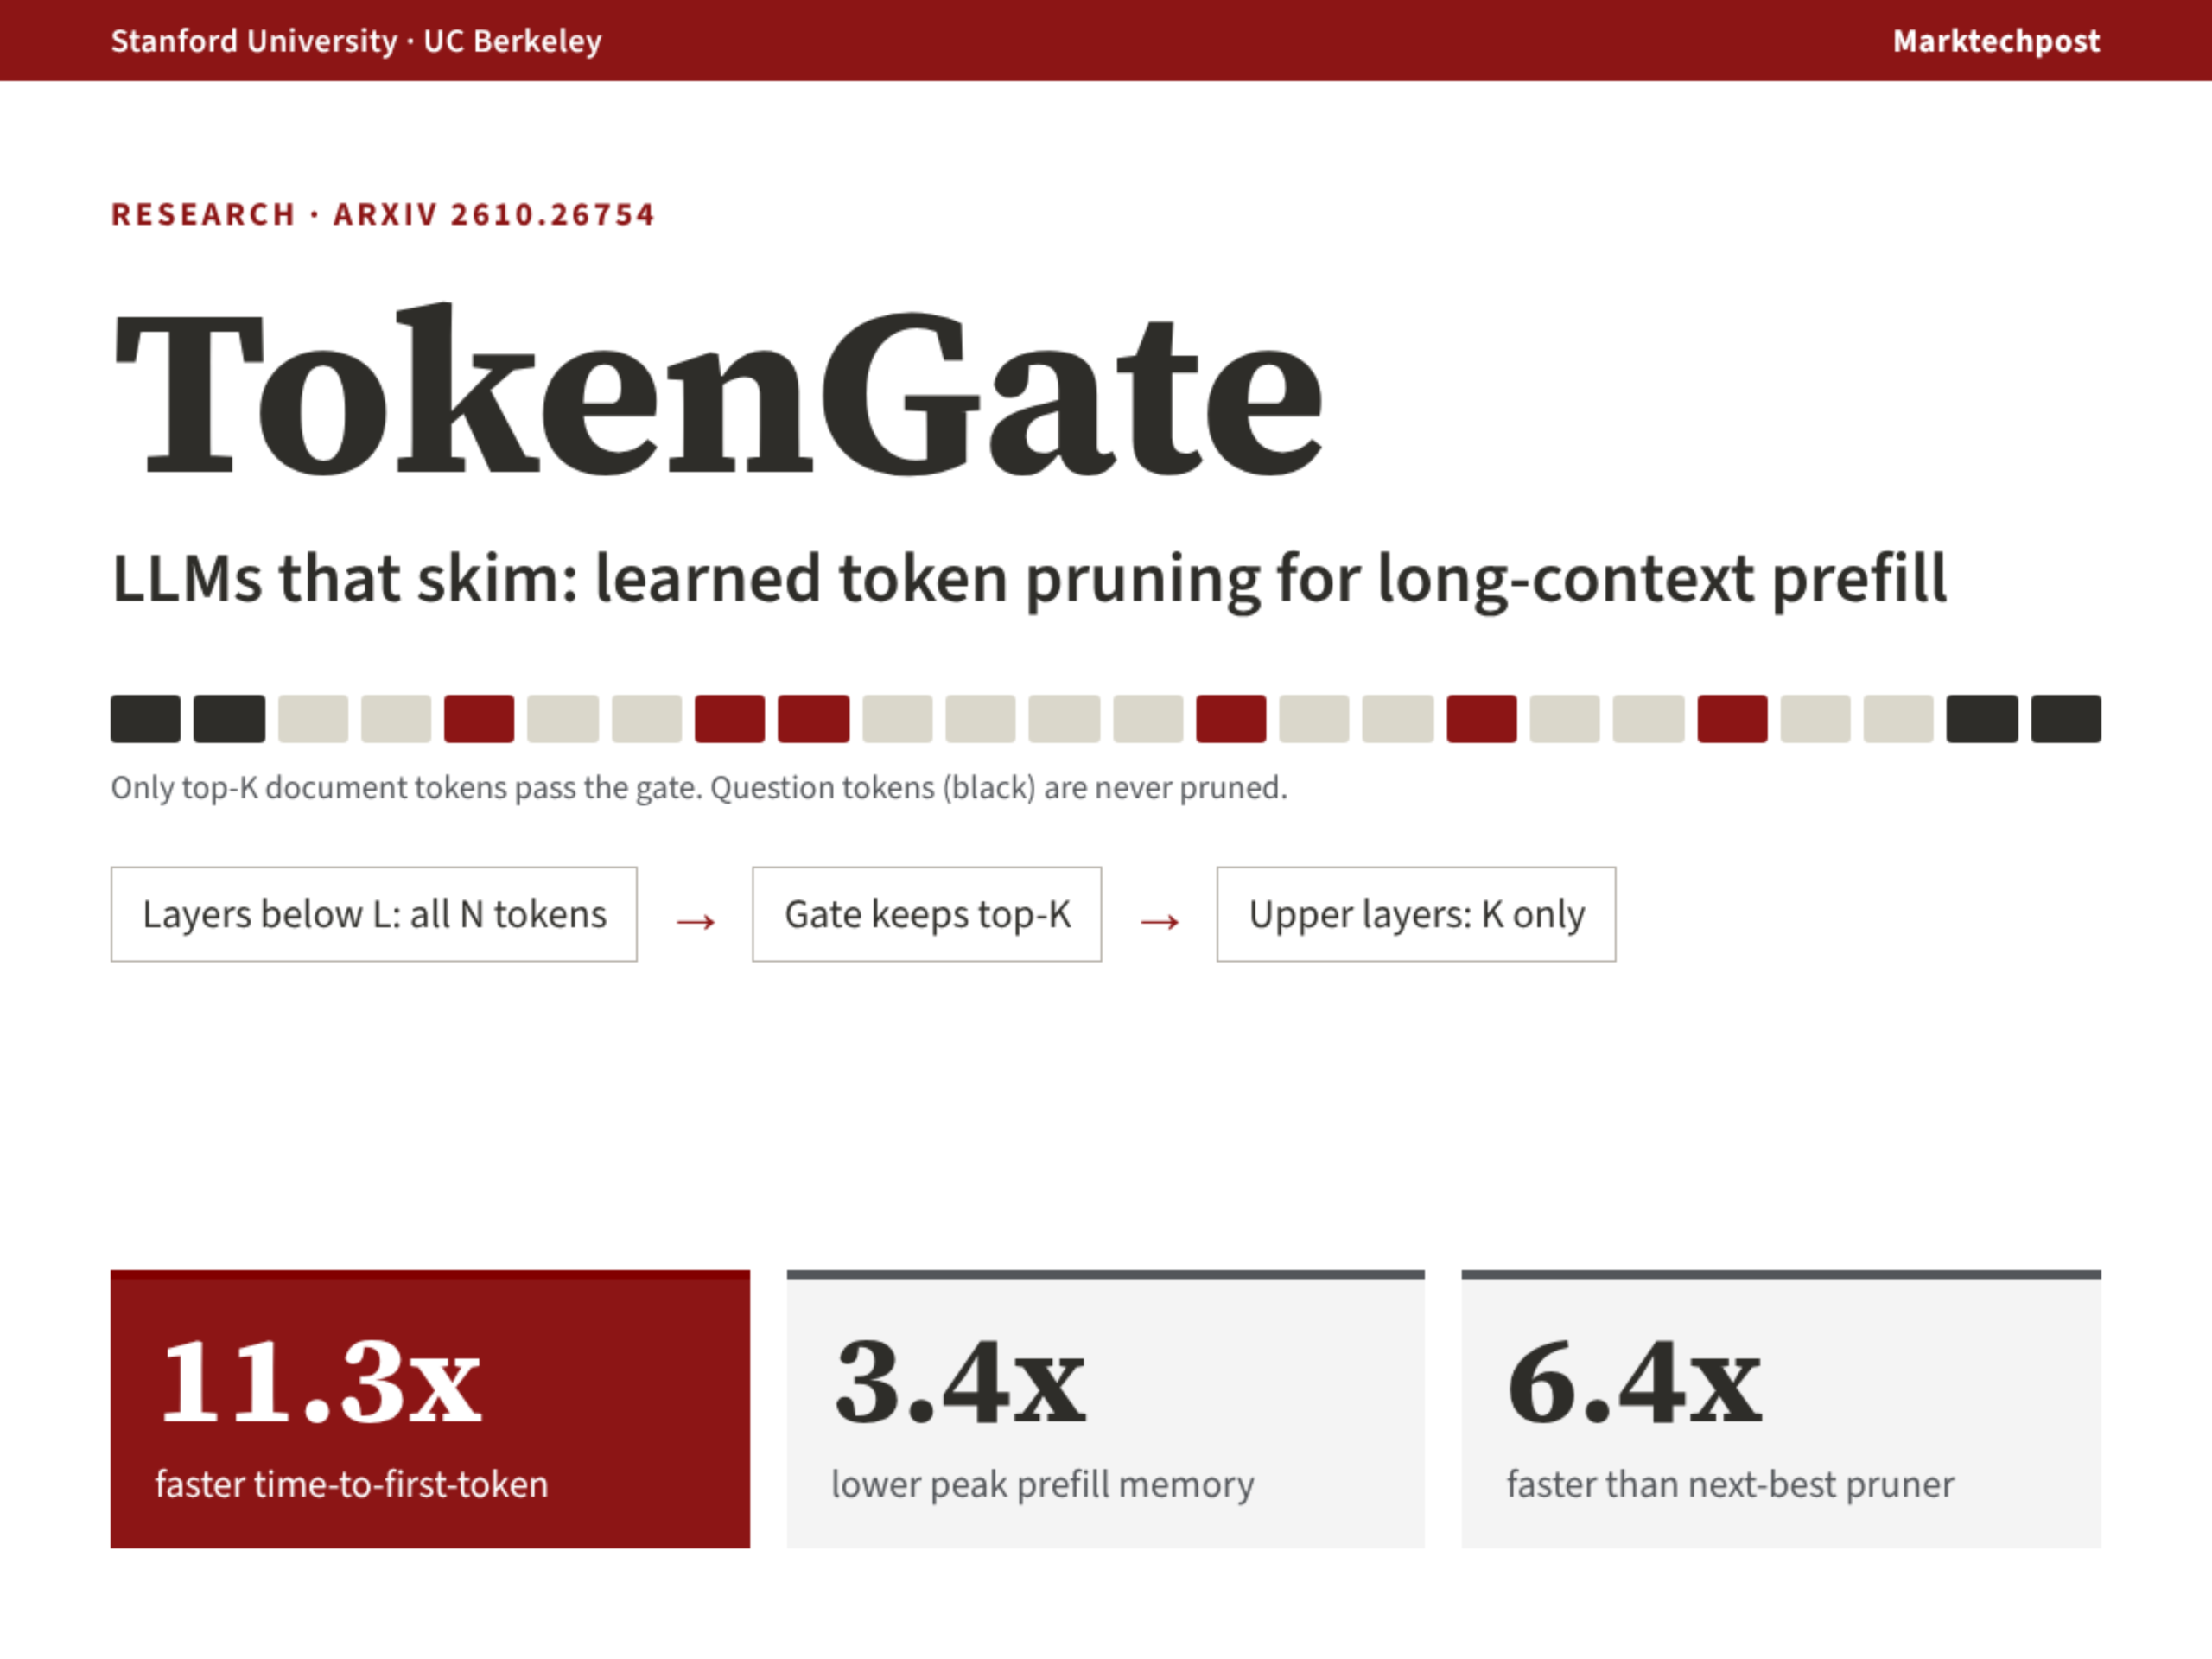
Researchers from Stanford University and the University of California, Berkeley have introduced TokenGate—a plug-and-play, learnable token-pruning module designed for existing large language models (LLMs). This approach accelerates the first-token generation time (TTFT) for long-context prefill by 1.4 to 11.3 times without sacrificing accuracy, while reducing peak memory usage by 1.5 to 3.4 times. The associated code and checkpoints have been made open source.
On October 24, 2026, Sebastian Raschka published an eight-part, over-11-hour hands-on video course on Python and PyTorch in Ahead of AI magazine (magazine.sebastianraschka.com), systematically covering the evaluation of inference models, scaling during inference, reinforcement learning (RLVR), and knowledge distillation, with all methods implemented using the pre-trained Qwen3-0.6B model.
Why it matters:This course is the author’s advanced technical educational offering, following “Building Large Language Models from Scratch.” It focuses on the core evolutionary direction of today’s mainstream LLMs—enhancing inference capabilities—covering the entire technical pipeline from setting up the foundational environment to GRPO reinforcement learning and self‑distillation. The author explicitly states that all implementations are “hand‑crafted from scratch,” fully reproducible, and highly instructive with significant engineering reference value.
AWS has released a technical solution that leverages the Kokoro-82M text-to-speech model hosted on SageMaker, using bidirectional WebSocket to enable AI agents to generate text and synthesize speech simultaneously, significantly reducing end-to-end speech response latency. The solution offers two audio back‑transmission methods—Base64‑SSE and unified binary transmission—and is explicitly labeled as “proof-of-value,” meaning it has not yet reached production‑ready status.
This article is the first in a series of technical blog posts jointly published by Hugging Face and Amazon, systematically introducing how to use TorchNeuron on AWS Trainium AI accelerator chips for PyTorch model inference performance analysis. It covers the principles of Neuron backend integration, methods for configuring torch.profiler, the use of NeuronConfig and NeuronProfiler tools, and visualized tracing with Neuron Explorer. Additionally, using RMSNorm as an example, it compares the device‑time differences among three implementations: plain PyTorch, the built-in torch.rms_norm fusion, and torch.compile’s automatic fusion.
i14 has launched the Laplace 3B model with 3.028 billion parameters, which replaces Softmax attention with Gated Linear Attention (GLA). During inference, its per-sequence recursive state remains constant at 29.5 MB, independent of context length. The model was trained and validated on a single AWS trn2.48xlarge instance (equipped with 16 Trainium 2 chips), achieving a training throughput of 120,000 tokens per second and an inference throughput of 11,544 output tokens per second (with 1,280 concurrent sequences). All performance metrics are based on internal measurements conducted by i14 and the AWS GenAIIC team.
Hugging Face has released TorchTPU, providing native TPU backend support for PyTorch, enabling libraries such as Transformers and Diffusers to run directly on TPUs without relying on torch_xla or migrating to JAX.
PyTorch 2.15 brings a major MPS backend upgrade to Apple Silicon Macs, natively supporting FP8 tensor operations on macOS for the first time, boosting MoE model decoding speed by 5–6.5 times, reducing peak video VAE memory usage from 270 GiB to 8 GiB, and migrating numerous operators from MPSGraph to dedicated Metal kernels.