Skip to content
AI NEWS JOURNAL
AI, IN PERSPECTIVE

Search AI news

Search headlines, summaries and articles to connect the dots.

Newest first

b12202

The llama.cpp v1.220.2 release introduces enhanced BF16 precision support across multiple components, aligning with reference implementations by moving specific operations like GLM4 family projections, MiMoVL vision matmuls, and Qwen3-TTS speaker encoder conv1d to BF16 where appropriate. Backends such as CUDA, Hexagon, OpenCL, WebGPU, and Vulkan now uniformly handle GGML_PREC_BF16 similarly to F32, while CPU, SpaceMIT, and ET backends extend flash attention support to BF16 with F32 accumulation. Flash attention tests now include BF16 cases, and the KQ multiplication in Llama is updated to request BF16 precision. A TODO remains in clip.cpp for future work.

v0.44.0

ComfyUI v0.44.0 introduces multiple new partner nodes for tools like Patina, VEED, BFL, Ideogram, Pruna, MiniMax, Topaz, Sonilo, and OpenAI, adding features such as higher resolution video upscaling, context window editing, and new models. Enhancements include support for ProRes and custom chroma subsampling in video saving, improved frontend handling with pinned versions, optimized tensor comparisons, and better VAE compute dtype control. Performance optimizations address redundant concatenations and memory management, while bug fixes resolve crashes related to VAE decoding and prefetch queue cleanup. The release also updates workflow templates, embedded documentation, and default settings, with contributions from new developers.

Anthropic files its prospectus, with违规 users contributing at least 5% of its revenue; the Hurun Rich List’s top 100 includes AI heavyweights such as Liang Wenfeng | What’s happening in the AI world again?

1. GPT-6.1 Terra, better suited for workers, has launched, with API prices cut in half and faster computer operations On October 26, OpenAI released GPT-6.1 Terra, focusing on enhancing visual comprehension, computer operations, factual accuracy, and programming capabilities, ....

Anthropic发招股书,违规用户贡献至少5%收入;胡润富豪榜百强名单,梁文锋等AI大佬纷纷上榜 | AI圈又发生什么了
Timeline and related coverage

MiniMax M3.1Flash release sparks “questionable results” concerns: high scores on old questions, failure on new ones, and an illusion rate as high as 92.8%

On October 19, 2026, MiniMax released its low-cost large model, M3.1Flash, which scored 42 points in comprehensive evaluations and boasts a 70% reduction in cost compared to the previous generation. However, it immediately faced accusations of “cheating on exam questions”: on AA’s publicly available past papers, it nearly achieved a perfect score, yet continued to produce the original answers even after the question stems were rewritten. Reviewers such as Cat Boss and Binkg pointed out that its performance on old and new questions is sharply divided, token consumption is abnormal, and its hallucination rate in knowledge tests reaches as high as 92.8%. On October 23, MiniMax open-sourced the model weights for independent verification, but the mechanisms behind its question-identification capabilities and the reasons for discrepancies in Chinese–English responses remain unresolved.

Why it matters:This report is based on multi‑party empirical testing (including Binkg’s re‑title experiment, the author’s replication, and a dual evaluation comparison between AA and Plotly‑Mila), verifiable data (token counts, prices, accuracy/hallucination rates), and contradictions in model behavior (English errors vs. Chinese correctness, stable performance on old tasks vs. collapse on new ones). It systematically lays out the core symptoms of the current credibility crisis in large‑model evaluations: high scores do not necessarily equate to strong generalization, and low‑price advantages create tension with the reality of model capabilities. The information source is a deep investigation authorized for publication by Titanium Media, complete with original test procedures, screenshot evidence, and timestamps, offering both timeliness and rich detail.
Timeline and related coverage

v0.43.0

## What's Changed * model_prefetch: syncrhonize all graph cleanups by @rattus128 in https://github.com/Comfy-Org/ComfyUI/pull/17178 * Add rope scaling support to MOSS-image by @kijai in https://github.com/Comfy-Org/ComfyUI/pull/17172 * [Partner Nodes] Renew partner-node sign-in tokens in API nodes by @dante01yoon in https://github.com/Comfy-Org/ComfyUI/pull/16943 * [Partner Nodes] feat(HeyGen): add HeyGen Voice instant clone and text-to-speech by @bigcat88 in https://github.com/Comfy-Org/ComfyUI/pull/17043 * [Partner Nodes] feat(ClarityAI): add Crystal Video Upscaler node by @bigcat88 in https://github.com/Comfy-Org/ComfyUI/pull/17192 * [Partner Nodes] feat(BFL): add 2K/4K resolutions to FLUX 3 Video nodes by @bigcat88 in https://github.com/Comfy-Org/ComfyUI/pull/17200 * Support MOSS-image

Timeline and related coverage

Morning Briefing | Apple responds to cracks in the iPhone Duo’s inner screen / Anthropic files for a public IPO, aiming for the largest IPO in history / Xpeng’s Robotaxi receives approval for Level 4 demonstration operations

· OpenAI releases GPT-6.1 Terra, with API prices cut in half and faster computer performance · Apple officially rolls out iOS 27.2: Apple Music gets a new black-and-white design, and the iPhone Duo now supports the Apple Pencil · Huawei’s Enjoy series has cumulatively shipped over 160 million units #Follow iFanr’s official WeChat account: iFanr (WeChat ID: ifanr) for more exciting content delivered to you第一时间.

Timeline and related coverage

Tencent QClaw will be discontinued on December 24, 2026, as Chinese tech giants accelerate the integration of their AI products into general-purpose assistants.

According to a report by Titanium Media on October 26, 2026, Tencent’s AI product QClaw will officially shut down on December 24, 2026, having operated for only 188 days since its public beta launch in March 2026; users will be redirected to WorkBuddy. This case exemplifies the widespread “quick launch, quick exit” pattern among eight leading Chinese AI companies—including Alibaba, Baidu, and ByteDance—across ten major AI market segments: standalone AI applications are rapidly giving way to general-purpose assistants, with the industry’s focus now shifting toward personal intelligent agents.

Why it matters:The material is based on timely reports published by Titanium Media (tmtpost.com), with a publication time of 2026-10-26T23:23:04Z, which predates the shutdown date and aligns with the site’s time zone (Asia/Singapore). The content covers verifiable entities, specific timelines, and cross-company behavioral patterns, without relying on external sources that were not provided.

Timeline and related coverage

Kimi releases K3.1 Pro, offering more features at a lower price to challenge Opus 5.5.

Author | Yu Hang Yuan Editor | Jing Yu On the morning of October 23, Kimi officially posted a 24-second video on X and its Video Account. The scene shows a retro‑style vintage computer, with Kimi Code running on the screen and lines of Three.js code being typed into the terminal, generating a complex 3D scene. Keen-eyed netizens quickly spotted the answer in the model bar at the top left: “Model: Kimi K3.1.” Kimi’s official teaser video for K3.1 | Image source: X @Kimi_Moonshot Using an antiquated machine to run some of today’s most cutting‑edge 3D code—this stark contrast itself conveys what Moonshot AI is trying to say. A dozen hours later, just after midnight on October 24, right on Programmer’s Day, Kimi K3.1 Pro officially launched, accompanied by a Highspeed version that’s two to three times faster. The company promises that the full model weights will be released before November 4. More than three months have passed since the previous generation, K3, was unveiled. In those three months, Moonshot AI has experienced more than most companies see in an entire year. 01 “More for the same price”—what’s new in 0.1? First, let’s clarify what K3.1 Pro is. It isn’t an entirely new model. Moonshot AI explicitly states that K3.1 Pro is a post‑training variant of K3; the underlying architecture remains unchanged—still a hybrid expert architecture with 2.8 trillion total parameters and 104 billion activation parameters, still featuring a 1 million‑token context window, and still natively supporting image and video inputs. What has changed is the post‑training phase. According to the company, they’ve invested “significantly increased post‑training compute power,” conducting large‑scale joint reinforcement learning across hundreds of downstream tasks. To support this, they completely reengineered the underlying infrastructure—including the reinforcement learning framework, sandbox environment, and long‑context reasoning capabilities. In essence, the same brain has been retrained from scratch on how to perform its tasks. The results are reflected in benchmark scores. On Terminal‑Bench 4.0, which evaluates coding agents, K3.1 Pro achieved 65.7%, surpassing GPT‑6 Astra’s 58.2% and falling short of Claude Opus’s 66.4% by less than one percentage point. As for the previous generation, K3…

Timeline and related coverage

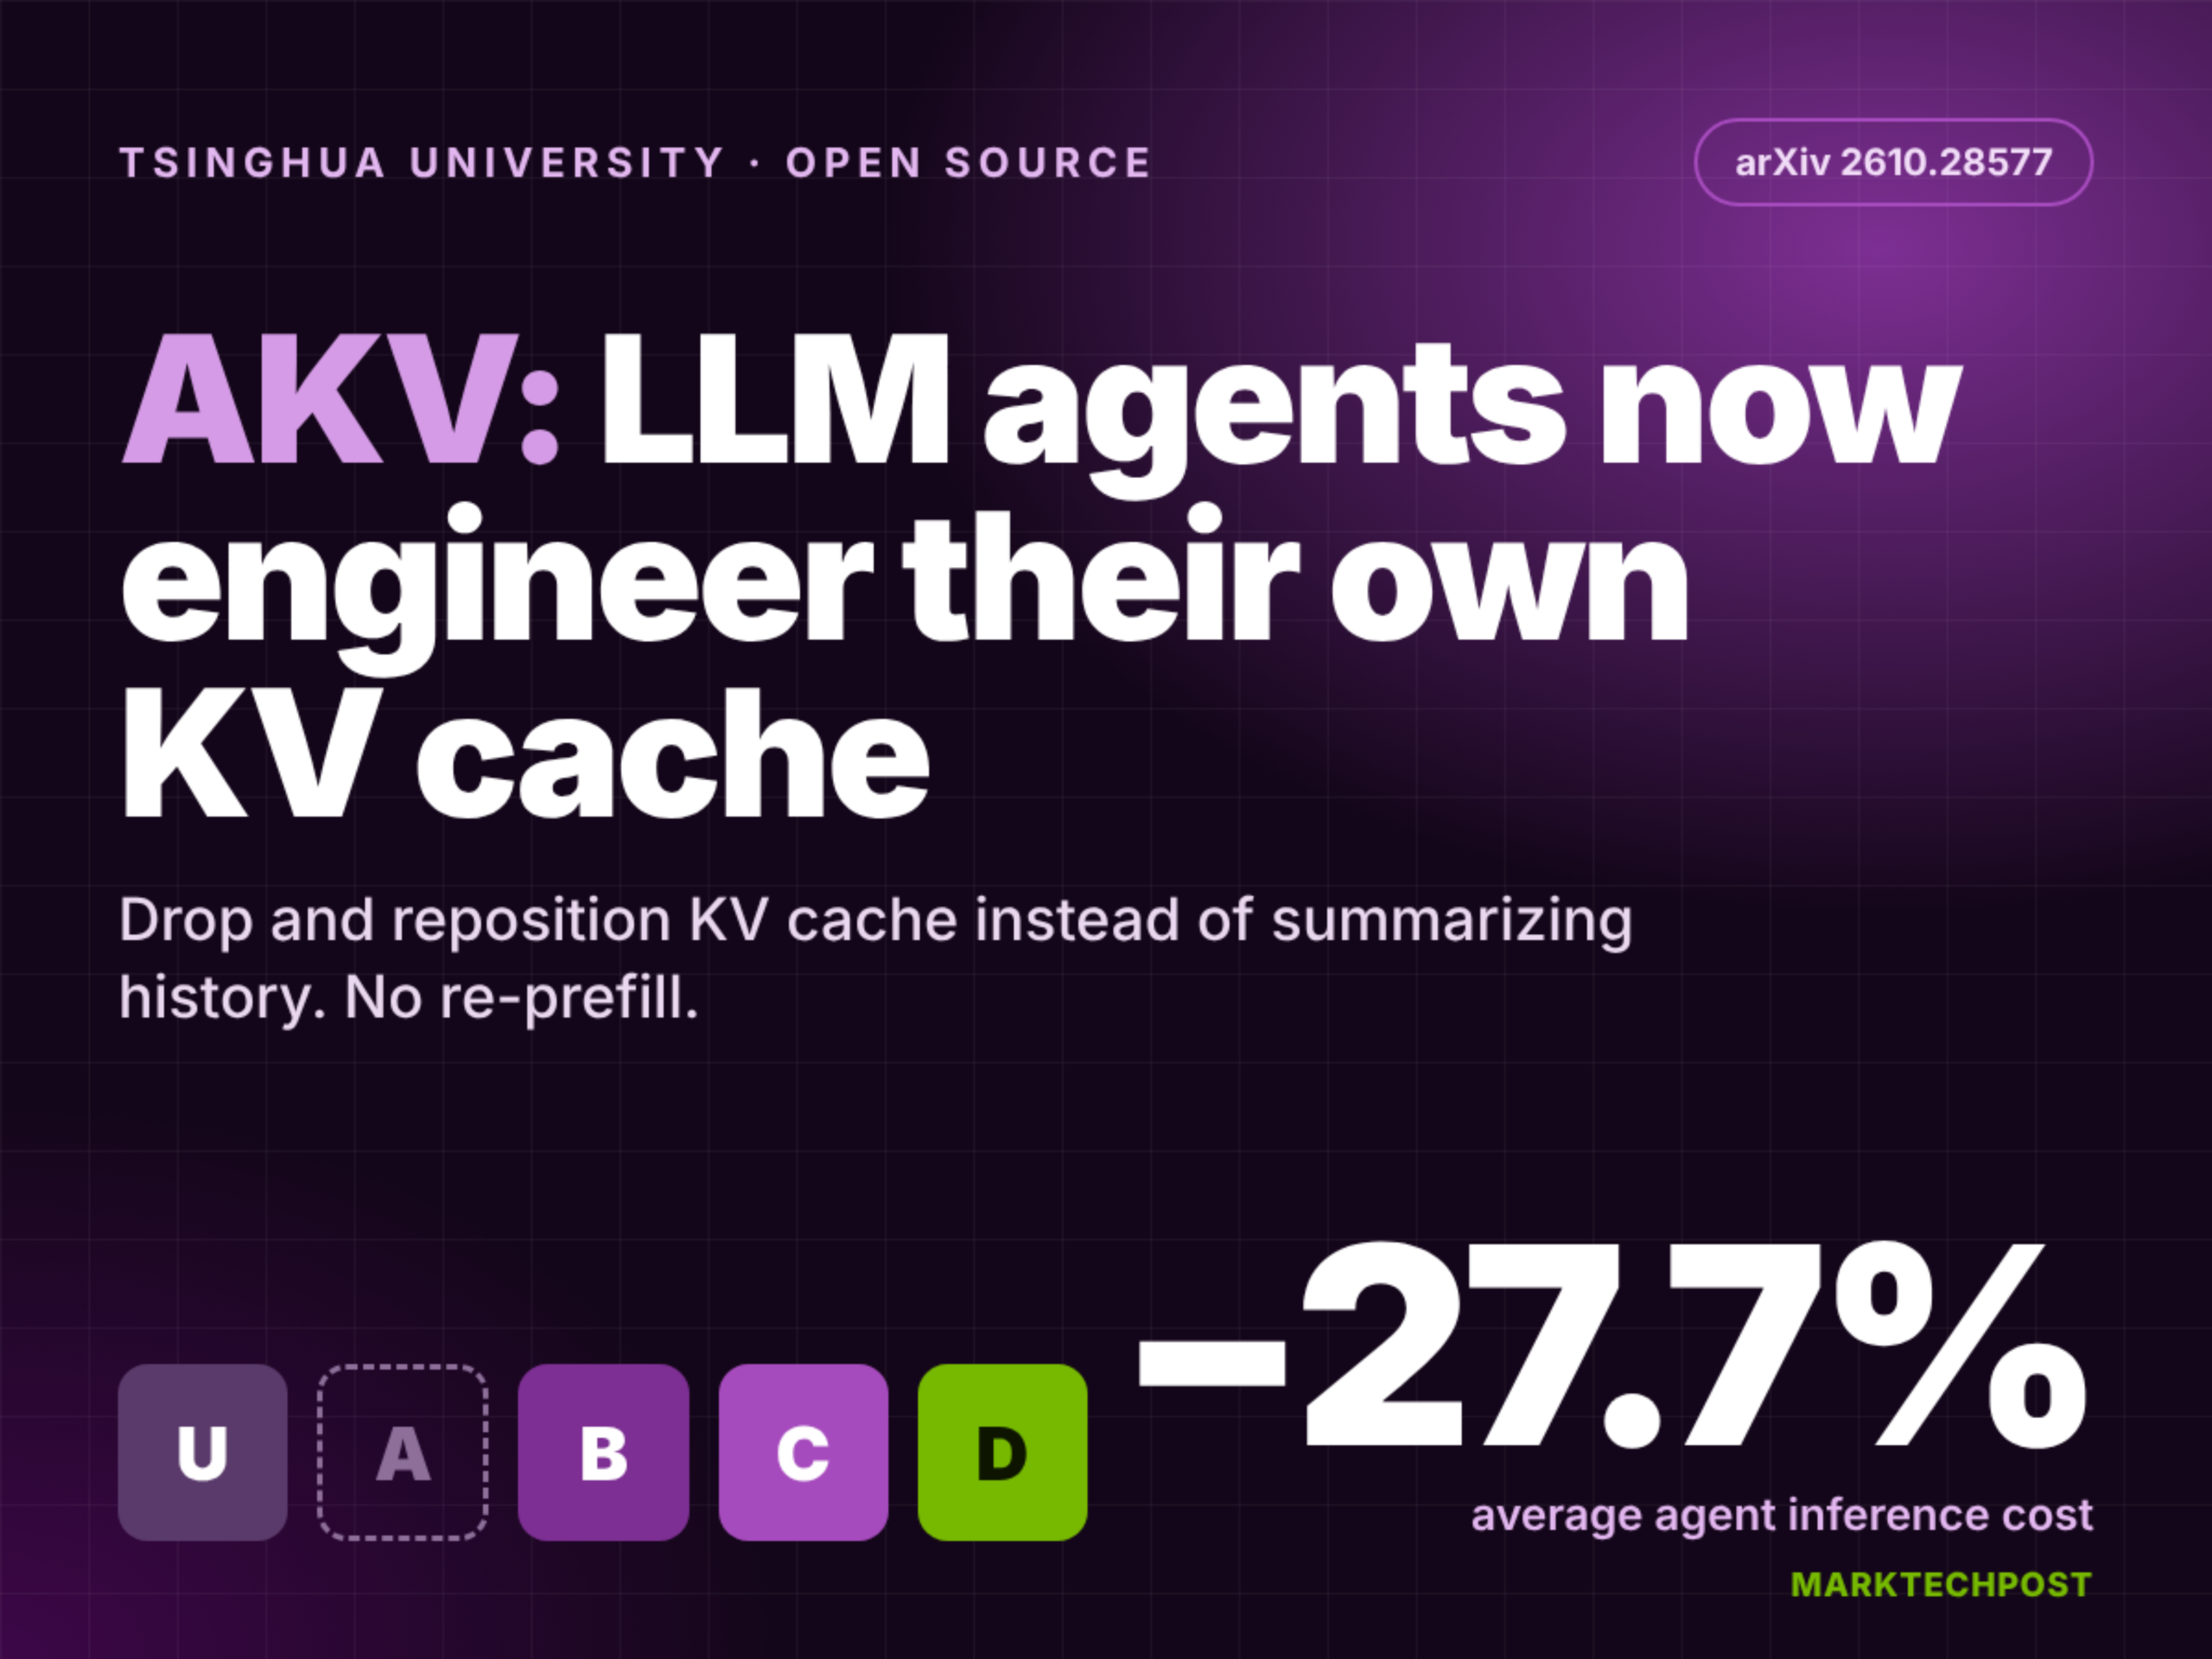
Tsinghua University and The Chinese University of Hong Kong jointly open-source AKV: an engineering service system for KV caching tailored to LLM agents.

On October 26, 2026, researchers from Tsinghua University and the Chinese University of Hong Kong open-sourced AKV—a KV cache engineering server built on SGLang and specifically designed for large language model (LLM) agents. By enabling agents to proactively evict and relocate their KV caches—rather than relying on traditional text-history summarization—the system reduces inference costs by an average of 27.7% across four agent benchmarks and improves task scores by 1.7 points on average. The code is licensed under the Apache-2.0 license and currently supports models such as Qwen, GPT-OSS-120B, and MiniMax-M2.7.

Tsinghua AI Open-Sources AKV, a Cache Engineering Server for LLM Agents on SGLang

Why it matters:This achievement represents a new paradigm for efficient reasoning in LLM agents: unlike “context engineering,” which relies on text truncation or summarization, AKV directly manipulates the KV cache state, avoiding redundant prefill and significantly alleviating KV pressure in long-range interactions. Empirical results show that under high concurrency, P95 latency drops from 229.9 seconds to 30.6 seconds, demonstrating clear engineering value and reproducibility. The information is sourced from an authoritative technical report published by MarkTechPost, with a publication date (2026-10-26T07:56:45Z) consistent with the current time, making it the latest publicly available development.

Timeline and related coverage

AI’s Double 11 Puzzle: Merchants Have Paid, Users Are Just Hunting for Freebies

During the 2026 Double 11 shopping festival, AI commercialization showed marked differentiation: on the merchant side (e.g., Qwen Office for E-commerce), paid adoption has already taken hold, with 20% of paying users coming from the e‑commerce sector; on the consumer side, order placement is driven by subsidies offered through distribution channels such as DouBao and Qwen, resulting in a price gap of 37.5%, yet user trust remains low (only 16.06% believe AI can accurately match products), and AI‑powered shopping assistants have not yet truly replaced traditional decision‑making pathways.

Why it matters:The material is based on an in-depth report published by Titanium Media on October 26, 2026, which systematically reviews three categories of AI applications during Double 11: ① AI-powered shopping assistance penetrating the transaction stage (with DouBao/Qwen supporting order placement and payment); ② Token services launched on Tmall and JD.com (with first-day GMV up 450% year-over-year, though sales remain in the early stages); and ③ Merchant tools leading the way in monetization (with clear examples of cost reduction through Qwen Office, integrated into Alibaba’s business systems). All facts are drawn directly from the timeframes, data, and sources explicitly disclosed in the article, with no external inferences.

Timeline and related coverage

Black October: A Comprehensive Overview of the AI-Driven Cybersecurity Crisis—From Its Peak to Defensive Response

Around October 21–22, 2026, over a span of approximately 48 hours, more than a dozen high‑severity AI‑related vulnerabilities and intrusion incidents were reported worldwide, including PHP2Shell, GitLab RCE (CVSS 10), NGINX/HTTP/3 DoS, LiteLLM password theft, eMudhra CA key leakage, and Quest Diagnostics medical data exposure. State actors such as Storm‑0940 leveraged open‑source intelligent penetration‑testing frameworks like ARTEX to launch large‑scale attacks. Concurrently, AI security defense systems were rapidly being developed, encompassing formal verification, open‑source patching agents, standardization of agent capabilities, and hardware‑level optimizations.

Timeline and related coverage

NVIDIA unveiled its full lineup of on-premises AI hardware at GTC Berlin: RTX Spark, DGX Spark, and DGX Station have now launched in Europe.

At the GTC conference held in Berlin in October 2026, NVIDIA officially unveiled three on-premises AI hardware platforms for individual users, developers, and enterprise customers: RTX Spark (a personal agent for Windows PCs), DGX Spark (a Linux development cluster), and DGX Station (a cutting-edge AI workstation), while simultaneously announcing numerous software updates, model support, and ecosystem integrations.

Timeline and related coverage

DeepSeek V4.1 Flash, MiniMax M3.1 Flash, and Mercury 3 have been released; model regulation in China and the U.S. has been upgraded; Anthropic has launched a public-interest fund and an AI legislation draft.

DeepSeek V4.1, Flash 1017, and two other new models have been released, but they remain in the early deployment phase; China and the U.S. are simultaneously strengthening AI governance: the U.S. Department of Homeland Security has banned DeepSeek-related products, while China plans to impose export approval for ultra-large-scale models; Anthropic has launched a public-interest equity fund and drafted a federal AI bill; industry infrastructure and security research are advancing in tandem.

Timeline and related coverage

DeepSeek V4.1 Flash, MiniMax M3.1 Flash, and Mercury 3 were released simultaneously, as debates over AI infrastructure and governance continue to intensify.

From October 16 to 19, 2026, three new models—DeepSeek V4.1 Flash 1017, MiniMax M3.1 Flash (Space Bunny), and Mercury 3 (Inception)—were released in quick succession. At the same time, the U.S. Department of Homeland Security ordered a ban on DeepSeek-related products, while China is drafting export control regulations for ultra-large-scale models, bringing the conflicts among the open-source ecosystem, computing infrastructure, and AI governance into sharp focus.

Timeline and related coverage

AINews Premium Review Issue 1: Surge in Open-Source Models, Tightening Geopolitical Regulations, and Controversy over Capability Verification

This issue focuses on key developments in the AI field in late October 2026: Meta unveiled its multimodal MoE model, Muse; Spark Open has been met with skepticism and labeled “dead”; performance, licensing, and deployment ecosystems among China, the U.S., and Europe are becoming increasingly divergent; China plans to introduce a draft export control regulation covering 23 categories of AI technologies; and several cutting-edge models have been released, accompanied by unverified performance claims and security concerns.

Timeline and related coverage